
A Green Health Check Does Not Mean Users Are Fine
A healthy process can still deliver a broken user journey. Learn how to combine probes, service telemetry, and end-to-end checks.
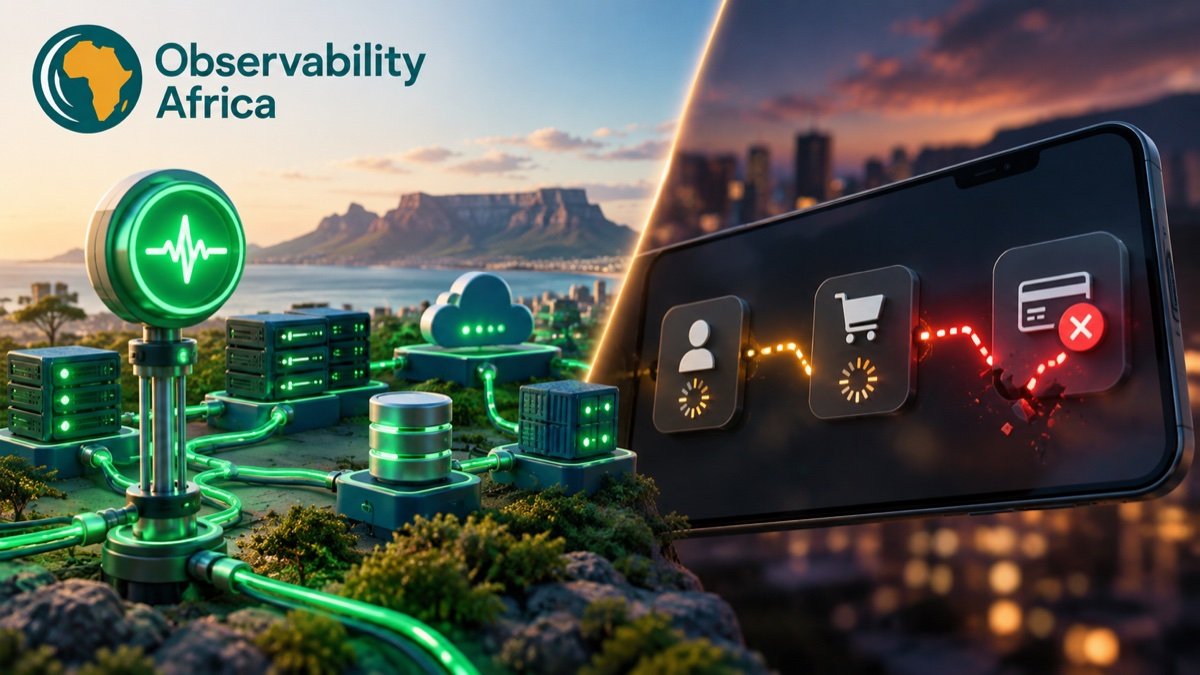
A green health check answers a narrow question. It does not prove that a customer can complete a payment, open an account, submit a form, or receive a confirmation.
Health probes are important. They help an orchestration platform decide whether a process has started, whether it should receive traffic, and whether it needs to be restarted. The problem begins when teams treat those signals as proof that the service is working for users.
Reliable operations require both views: the health of individual components and the success of the complete user journey.
What Kubernetes probes actually tell you
Kubernetes documents three different probe types.
- A startup probe determines whether an application has completed startup. When configured, it prevents liveness and readiness probes from running too early.
- A readiness probe determines whether a pod should receive traffic from Kubernetes Services.
- A liveness probe determines whether a container should be restarted because it is no longer making useful progress.
These are operational controls, not complete observability signals. A readiness probe can succeed while a downstream payment provider is failing. A liveness probe can succeed while every request takes too long. A startup probe can succeed even though required customer data did not load correctly.
The distinction matters because each probe can change system behaviour. Failed readiness removes a pod from service traffic. Failed liveness can restart a container. Incorrect probe logic can therefore make an incident worse.
Avoid one endpoint for every decision
Using one shallow endpoint for startup, readiness, and liveness is convenient, but it can hide important differences.
Liveness should answer whether the process can continue or recover without a restart. It should not fail merely because a remote dependency is slow. Restarting every pod during a database or network incident can reduce capacity and create a cascade.
Readiness can include conditions that make the instance temporarily unable to serve useful traffic. Even then, dependencies must be chosen carefully. Removing every replica because one shared dependency is unavailable does not restore the dependency.
Startup should allow enough time for slow initialization without weakening liveness checks for the rest of the process lifecycle.
Probe design should be based on the action that follows a failure. If the action would not improve the situation, the probe is measuring the wrong condition.
A healthy component can support a broken journey
A digital service normally depends on more than one process. A user may pass through a mobile application, an API gateway, an identity service, a business service, a database, and an external provider.
Each component can report healthy while the journey still fails because of:
- incorrect routing or configuration
- expired credentials or certificates
- incomplete data replication
- a slow external dependency
- a broken message or callback path
- client-side errors
- a business rule that rejects valid requests
- confirmation messages that never arrive
This is why Google SRE guidance distinguishes internal component monitoring from end-to-end tests. Internal metrics can show what each service believes is happening. End-to-end tests show whether the system produces the expected result from the user’s point of view.
Add telemetry around the probe result
A probe result is usually binary. Operational reality is not.
Around each service, monitor:
- request rate and error rate
- latency distributions, not only averages
- saturation and resource pressure
- dependency errors and timeouts
- queue depth and processing delay
- retries and circuit-breaker activity
- deployment version and recent changes
These signals help explain why a service moved from healthy to unready or why users are failing while probes remain green.
The service should also emit enough context to correlate a user-facing failure with the participating components. Consistent service identity, trace propagation, and controlled metric dimensions make that investigation faster.
Test the journey from outside the service
Synthetic monitoring can exercise a real endpoint or a complete workflow on a schedule. The test should verify the outcome, not only the HTTP status.
For example, a transaction journey might confirm that:
- authentication succeeds;
- an account or product can be retrieved;
- a transaction request is accepted;
- the final state changes as expected;
- a confirmation or callback arrives.
OpenTelemetry describes synthetic tests as part of the observability toolkit and supports carrying synthetic-test markers into telemetry. Marking test traffic allows teams to include or exclude it from operational analysis without confusing it with real customer behaviour.
Synthetic testing must be designed safely. Use controlled accounts, reversible actions, limited frequency, and clear separation from real financial or customer data.
Include real user signals when possible
Synthetic tests show whether a known path works from selected locations. They cannot represent every device, network, browser, or user behaviour.
Client-side telemetry can add information about real errors, device conditions, network quality, and user actions. This is especially valuable for mobile and web services used across varied connectivity conditions.
Privacy and data minimization remain essential. Collect only the context needed to understand reliability, and avoid capturing sensitive user content.
Build one layered reliability view
A useful dashboard should connect three levels:
- Platform health: restarts, readiness, CPU, memory, and infrastructure events.
- Service behaviour: traffic, errors, latency, dependencies, and queues.
- User outcomes: synthetic journey success, real-user errors, and critical business completion rates.
Do not combine these into one vague green status. Keep each layer visible so responders can see whether the failure is local, distributed, or user-facing.
A practical review exercise
Choose one critical journey and review every health signal supporting it.
Ask:
- What does each probe test?
- What action follows when it fails?
- Can a shared dependency cause every replica to become unready?
- Can users fail while all probes remain green?
- Is there an external test of the full journey?
- Can responders trace that test through the participating services?
- Which real-user signals reveal conditions synthetic tests miss?
Then simulate one dependency slowdown and one incorrect business response. Confirm that the right signals change and that the system does not restart healthy processes unnecessarily.
Practical takeaways
- Use startup, readiness, and liveness probes for their distinct purposes.
- Design probes around the recovery action they trigger.
- Do not let a shared dependency turn liveness into a restart cascade.
- Combine probe state with traffic, errors, latency, saturation, and dependency telemetry.
- Test critical journeys from outside the service.
- Add privacy-conscious real-user signals where they improve diagnosis.
- Measure whether users complete important outcomes, not only whether processes are running.
Organizations that want an independent review of health checks, journey monitoring, alert quality, and failure behaviour can explore the Observability Africa audit and consulting service. Organizations may also support independent community education while Observability Africa retains editorial control.
Sources
- Kubernetes liveness, readiness, and startup probes
- Google SRE: Monitoring Distributed Systems
- OpenTelemetry client-side applications
- OpenTelemetry portable synthetic testing

About Abe Apithy
Abe Apithy is the founder of Observability Africa, a platform dedicated to helping telecom, fintech, and energy organizations design and scale resilient, high-performance digital infrastructure. His work focuses on enabling real-time system visibility, operational reliability, and performance optimization in environments where downtime, latency, and inefficiency…
Related guides
A Postmortem Is Not a Courtroom: How Lean Teams Learn Without Blame
A useful incident review explains how failure became possible. Learn how lean teams can build factual timelines, find contributing conditions, and turn lessons into verified improvements.
Alert Before the Budget Burns: Practical SLO Alerting for Lean Teams
In this guideStart with a user-centered objectiveUnderstand what burn rate meansUse two windows for urgent pagesSeparate pages from ticketsHandle low-traffic services differentlyDesign the alert […]

Your Telemetry Pipeline May Be Leaking More Than Errors
Observability data can become a security problem when it records more than engineers intended. Logs, traces, and metric attributes often cross application, network, storage, […]